Stuttgart, Germany · Available immediately

Raghul Raj Navaneethakrishnan

|

Software engineer specializing in hardware acceleration with CUDA and Deep Learning Optimization using Quantization, Kernel Fusion and Compilers.

0 points searched via custom CUDA KNN
0 on an RTX 3090
0 speedup, OpenCL vs single-thread CPU
0 latency cut, thesis inference pipeline

Building things close to the metal.

I write GPU kernels on the hardware, with the profiler open. My work spans dependency-free inference engines, hand-tuned CUDA libraries for point-cloud and image workloads, and production pipelines that combine PyTorch compilation with TensorRT to squeeze out every millisecond. Outside of GPU work, I've validated real-time embedded Linux behaviour on physical hardware and shipped ML pipelines for time-series generation in the automotive industry.

C++ & Systems

Hand-written kernels, zero-dependency engines, real-time constraints on embedded Linux (PREEMPT_RT).

GPU Acceleration

CUDA & OpenCL from first principles — tiled matmul, convolution, KNN, spatial sorting, reduction.

Applied Deep Learning

CNNs, UNet, Transformers & graph networks deployed through ONNX Runtime, TensorRT, and TVM.

Toolbox

Selected work

🌐 ↗

Inference Engine in C++/OpenCL from Scratch

A dependency-free UNet segmentation engine with custom OpenCL kernels written directly against the hardware — no cuDNN, no vendor libraries. Reaches a 600× speedup over a single-threaded CPU baseline on real image data.
  • C++
  • OpenCL
  • UNet
  • Kernel Optimization
🧮 ↗

CUDA Kernel Library

Hand-written CUDA kernels for tiled matrix multiplication, 2D/3D convolution, furthest point sampling, KNN, prefix sum, reduction, and histogram — with FP32/FP16 benchmarks against AVX-optimized CPU baselines.

  • CUDA
  • FP16
  • Point Cloud
  • Benchmarking
🧩 ↗

DDACS Dataset & Research Tooling

Assisted on the open-source DDACS dataset (32,071 FEM simulations) published to DaRUS with Croissant-format metadata, and built a FastAPI/Streamlit self-service tool for the IEH simulation pipeline with authenticated job submission.

  • FastAPI
  • Streamlit
  • FEM Data
  • Croissant
🔧

Yocto BSP Experience

Migrated a Yocto-based automotive BSP from Kirkstone to Scarthgap within Azure DevOps CI/CD pipelines.Integrated the Linux PREEMPT_RT patch and additional real-time patches, benchmarking scheduling latency to validate deterministic behaviour before release.

  • Yocto
  • PREEMPT_RT
  • JTAG/OpenOCD
  • Podman
  • Azure DevOps

GPU-Accelerated 3D Point Cloud Deep Learning

Universität Stuttgart · Feb 2026 – Jul 2026 · MT-3970

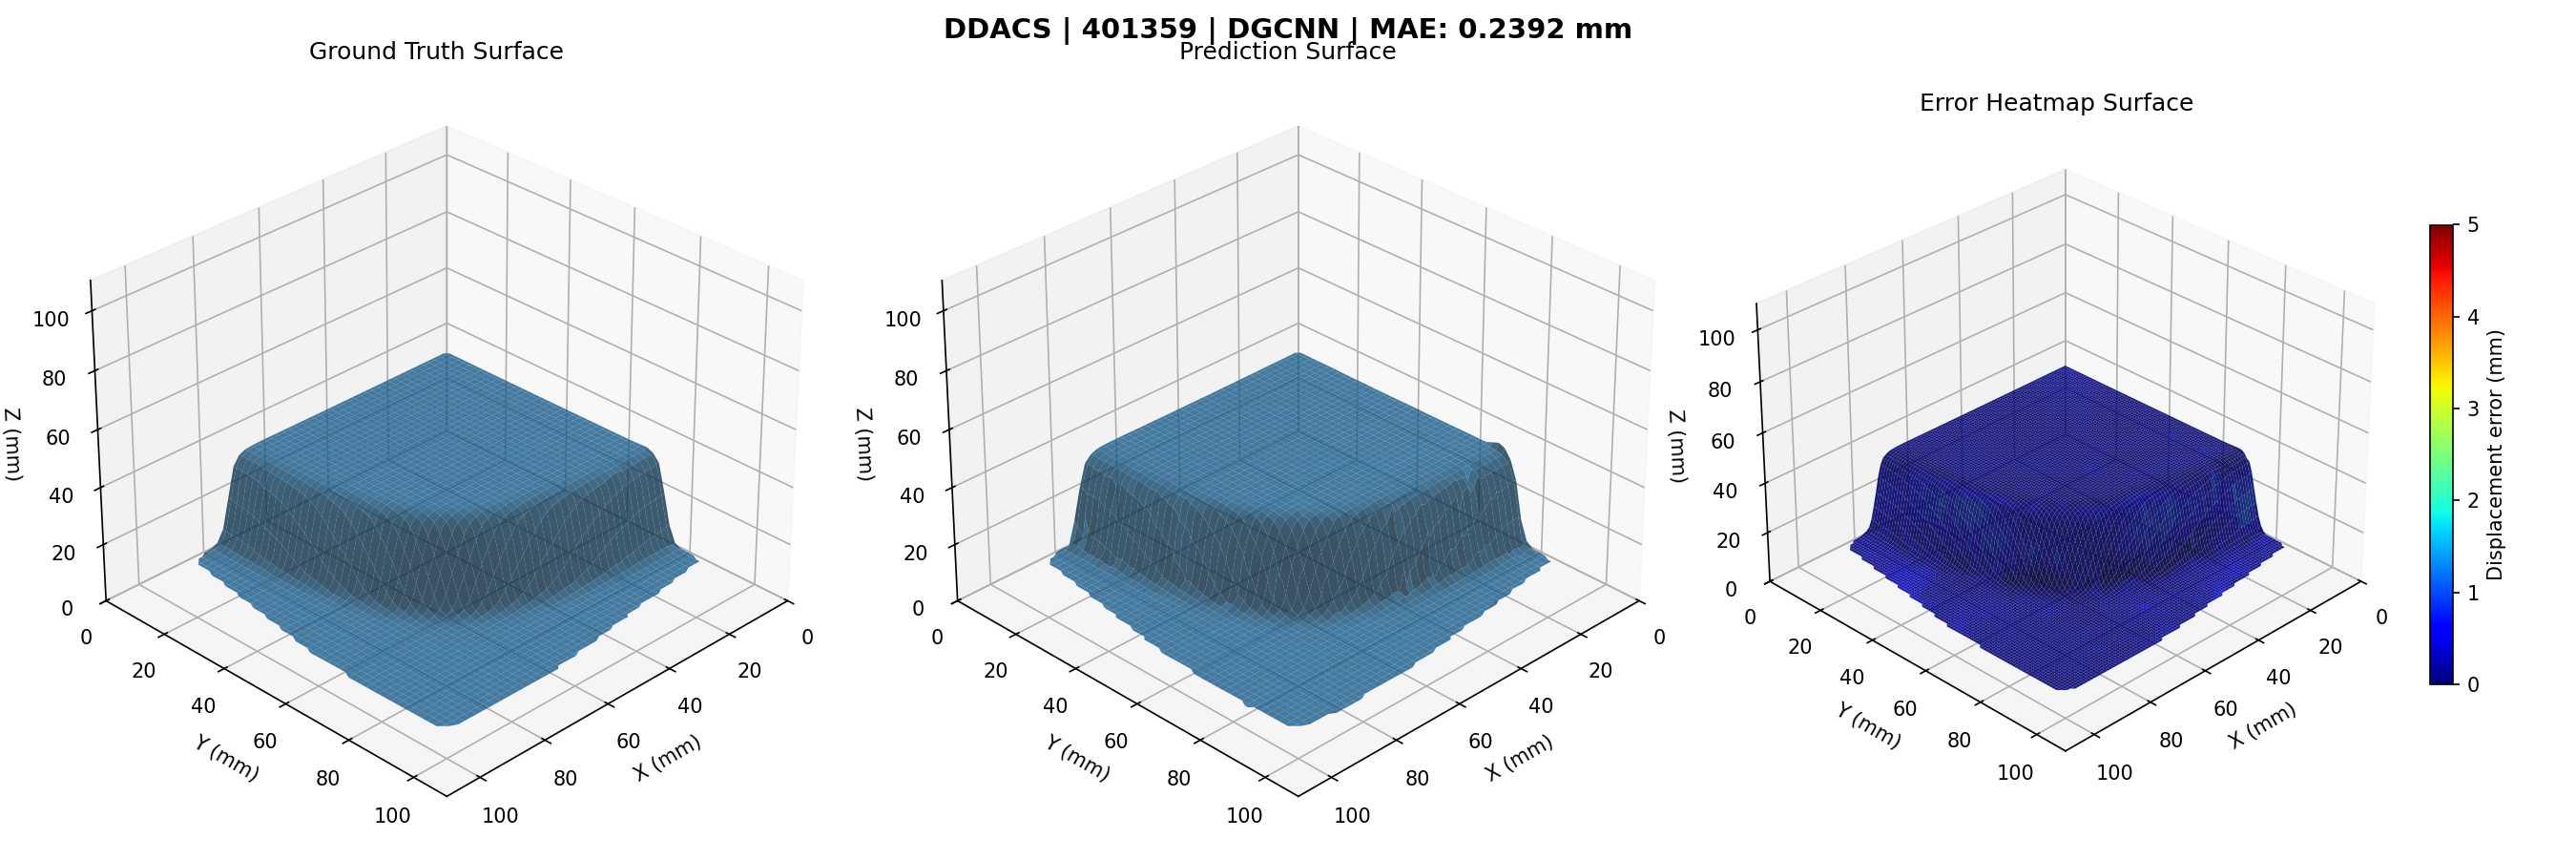
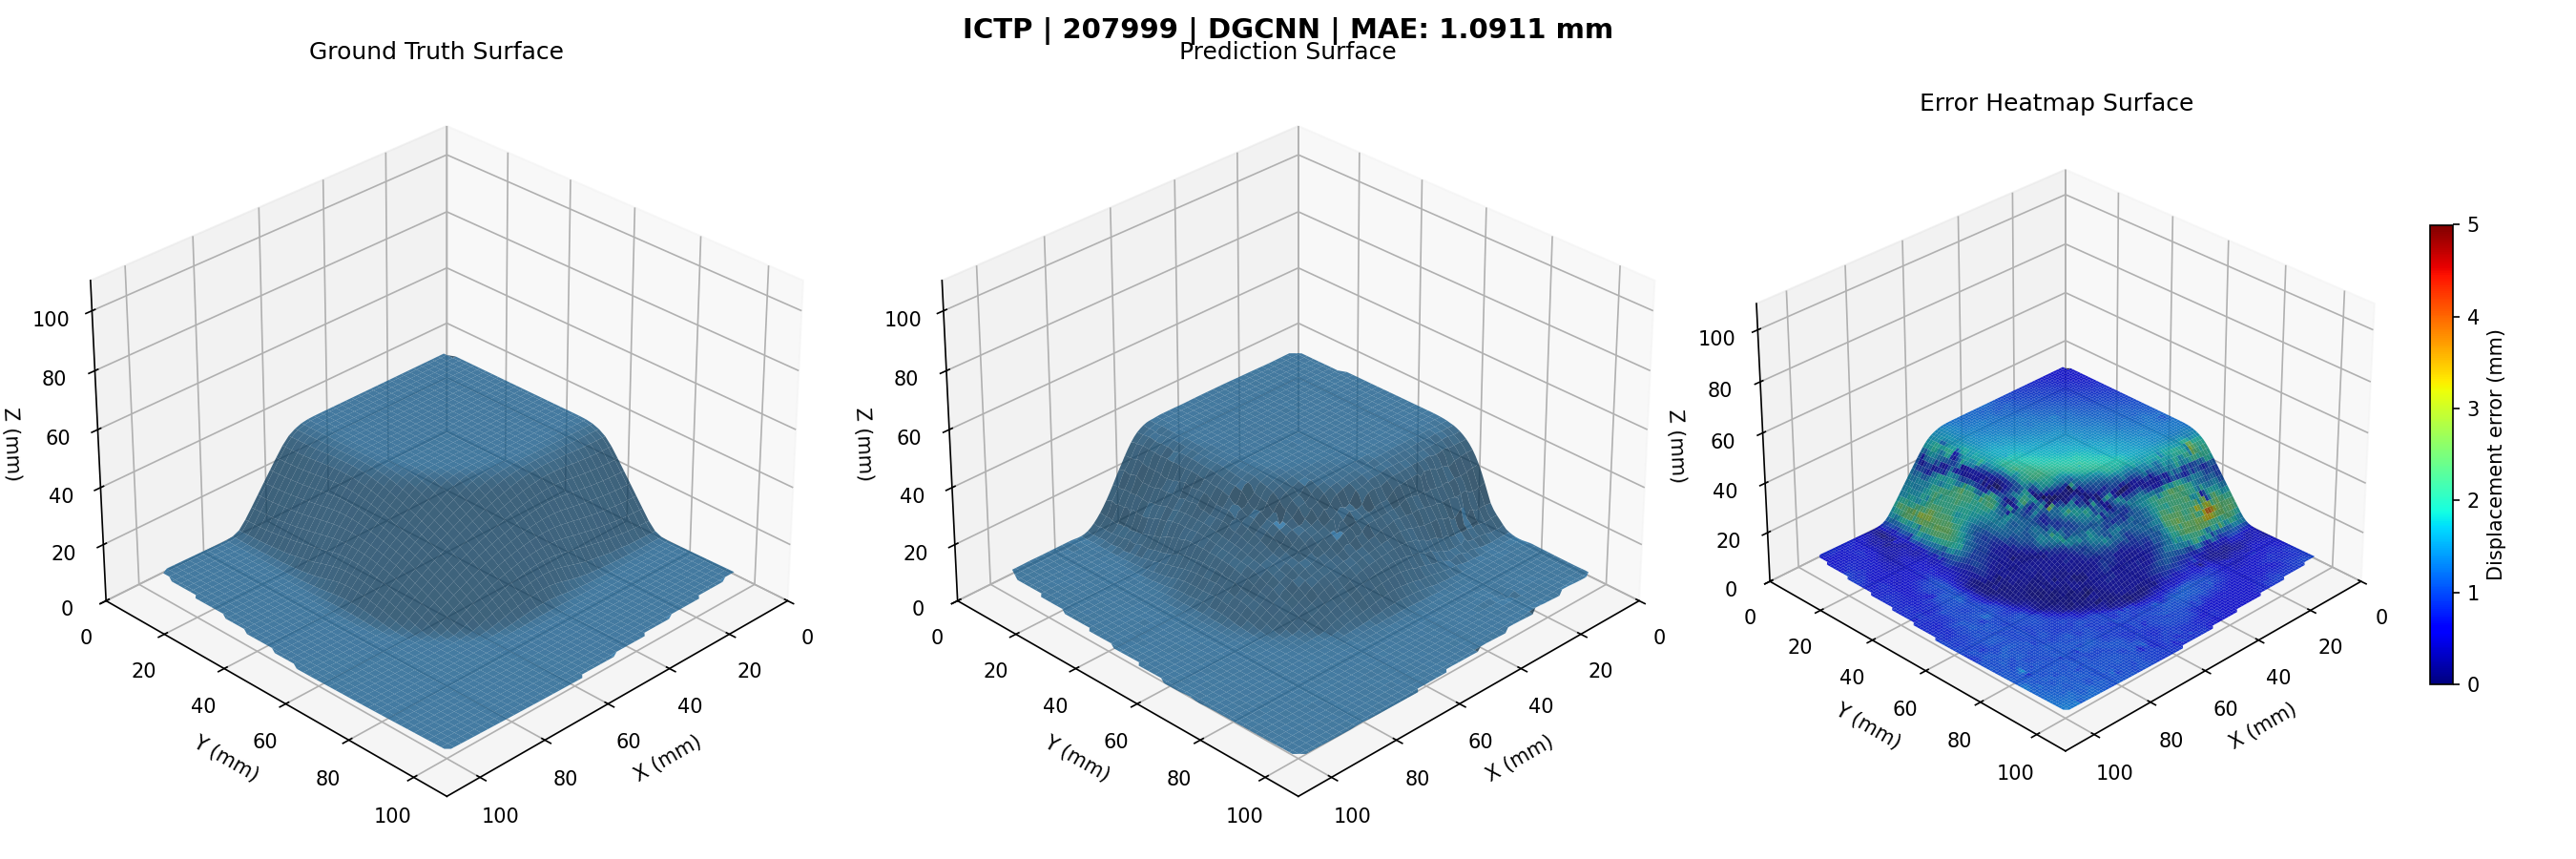
A DGCNN-based surrogate model with cross-attention, sinusoidal distance bias, and FiLM conditioning, designed to replace 1.5-hour FEM simulations of sheet-metal springback with a 15-millisecond prediction.

1.5 hrs Classical FEM simulation
→
15 ms DGCNN surrogate prediction

Model Design

DGCNN backbone augmented with cross-attention, sinusoidal distance bias, and FiLM conditioning for point-cloud springback prediction.

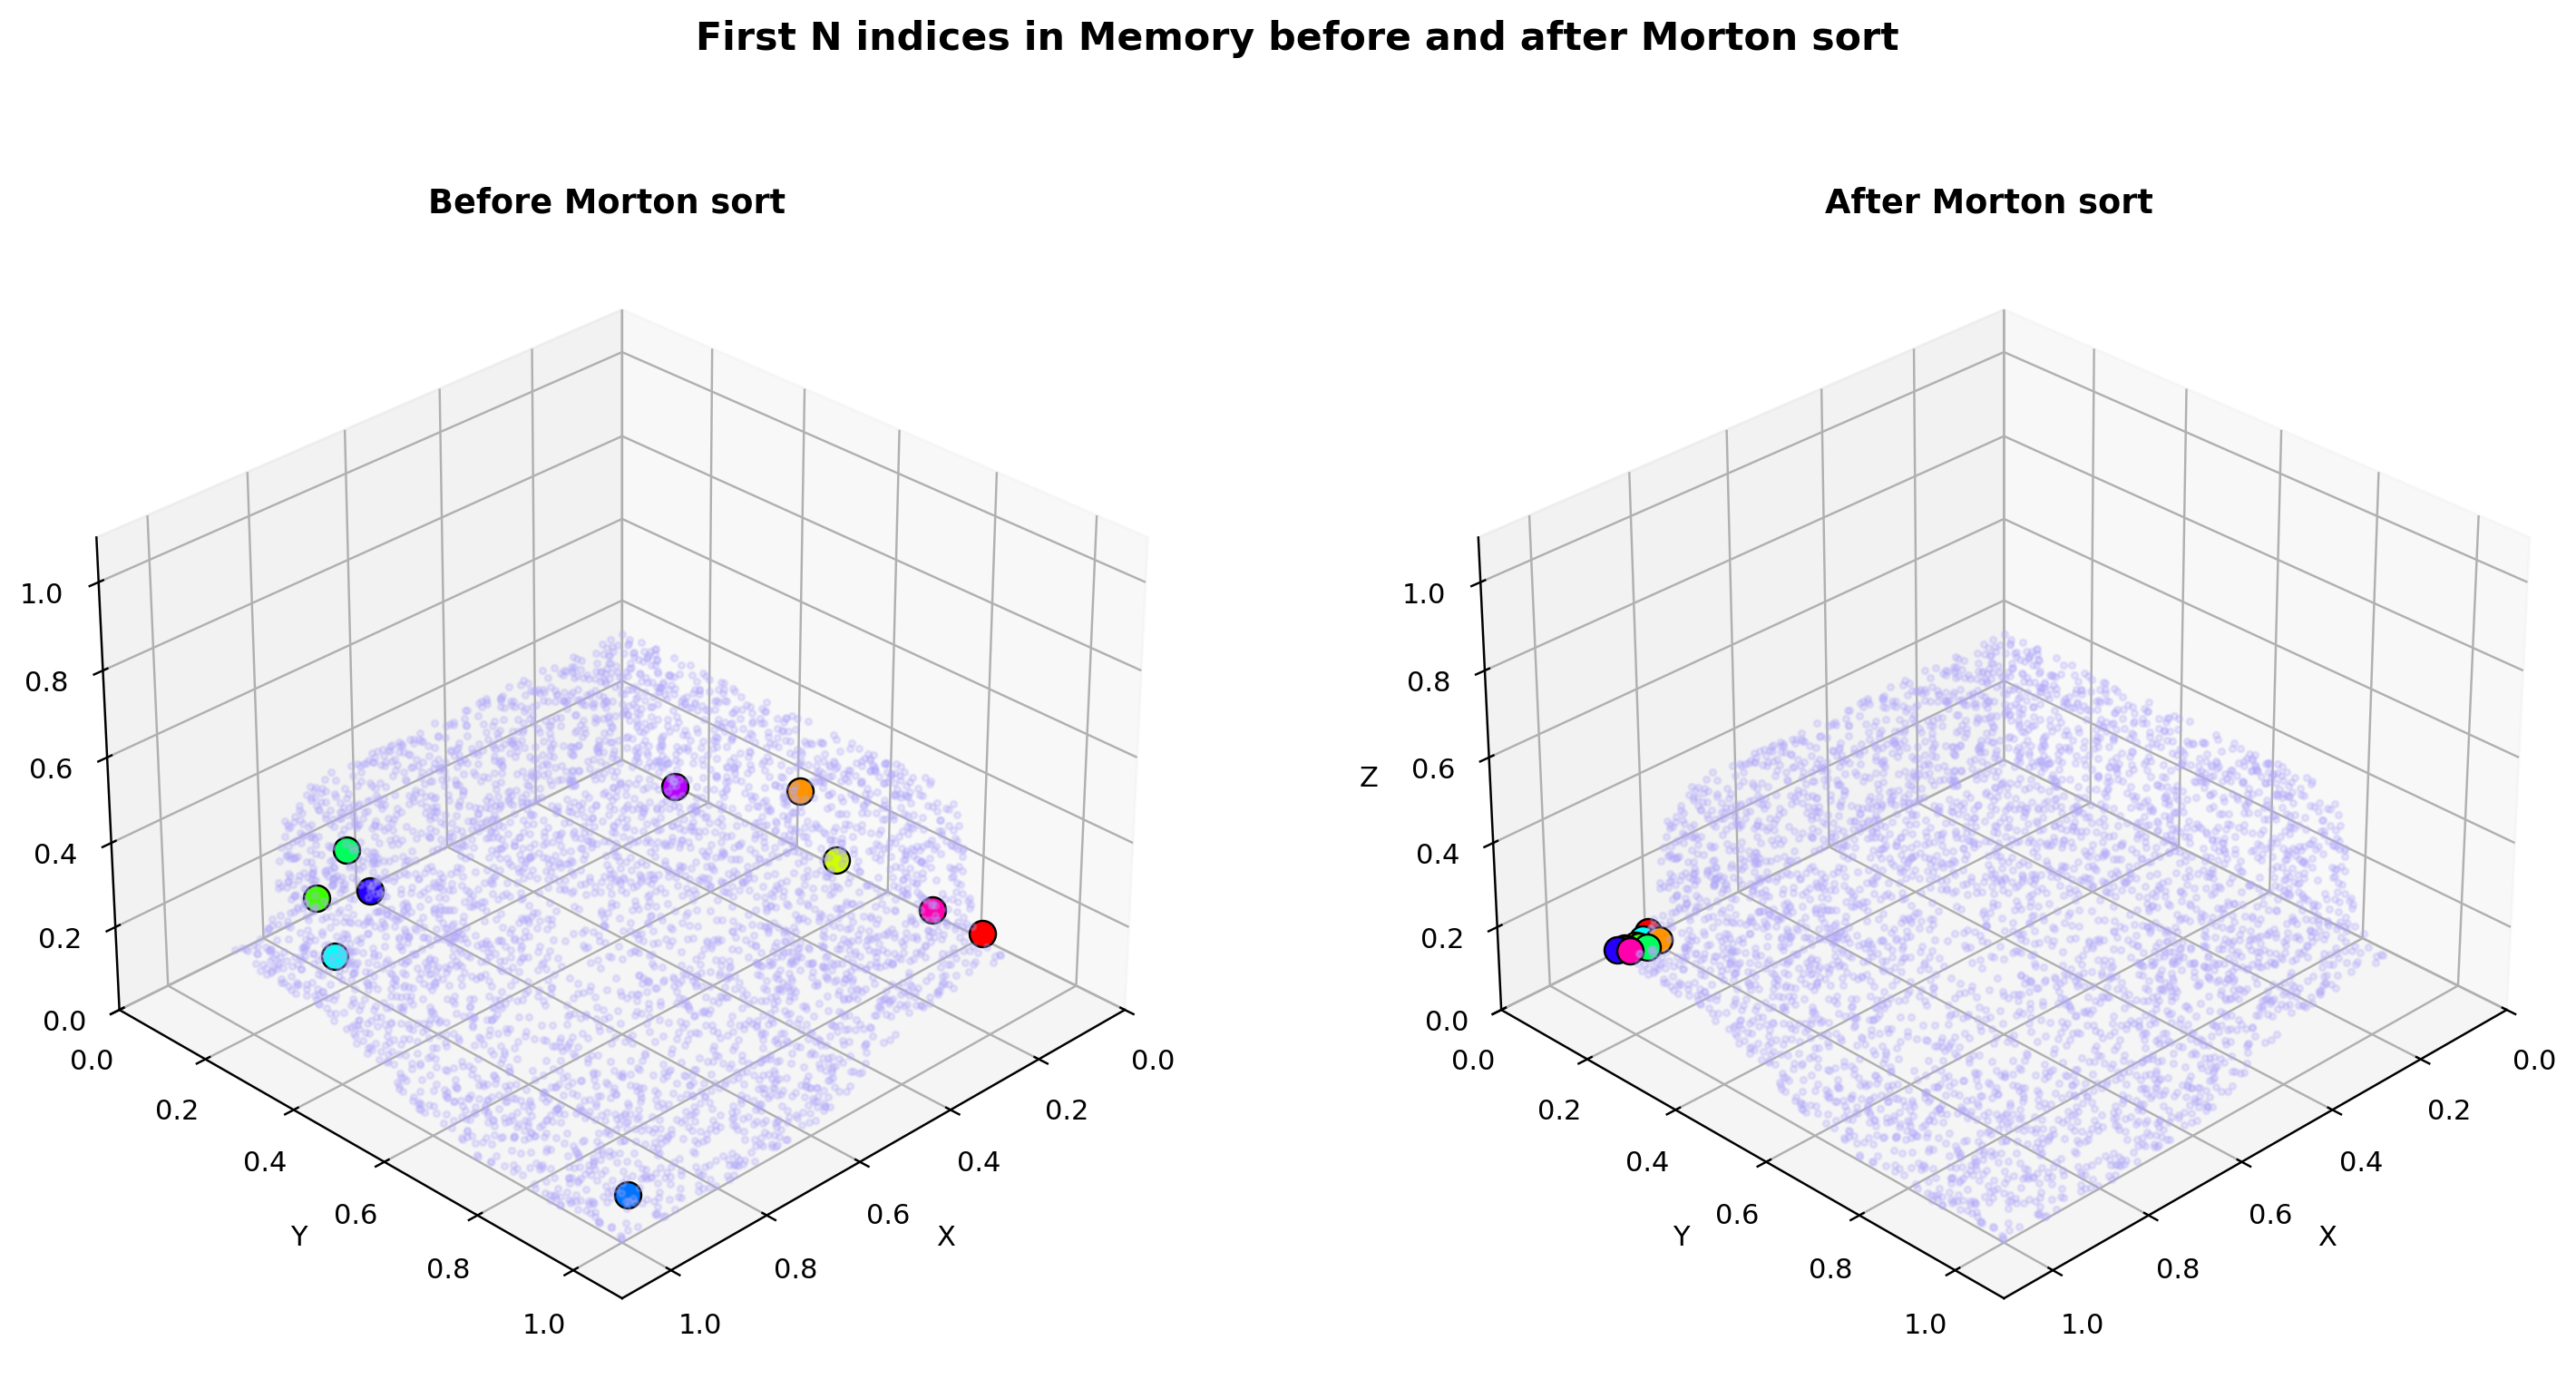
Custom CUDA KNN

Windowed Morton / Z-order spatial sorting to improve memory locality and throughput for K-nearest-neighbor search on point clouds.

Compiler + TensorRT

Combined PyTorch compilation with NVIDIA TensorRT, benchmarked against exact-KNN and library baselines (PyKeOps, cuML).

Baseline inference
60 ms
PyTorch compile + TensorRT
15 ms

4× latency reduction per sample, from 60 ms to 15 ms.

Timeline

Sep 2024 – Dec 2025

BSP Engineer — ETAS (Bosch Group), Abstatt

Validated real-time behaviour of embedded Linux (PREEMPT_RT) on physical hardware under strict timing constraints using JTAG/OpenOCD-based ARMv8 profiling. Hands-on hardware bring-up (Yocto BSP migration) and CI/CD pipelines (Azure DevOps).

Jan 2025 – Jun 2026

Research Assistant — University of Stuttgart

Assisted on the open-source DDACS dataset (32,071 FEM simulations) published to DaRUS. Built a FastAPI/Streamlit self-service web tool for the IEH research simulation pipeline.

Dec 2023 – Jun 2024

AI Software Engineer — Bosch Mobility GmbH, Ludwigsburg

Benchmarked LSTM, Transformer, 1D CNN, and Seq2Seq architectures for synthetic time-series generation. Designed a custom loss aligned to ISO 18571, improving correlation accuracy by 10% over generic MSE.

2019 – 2023

Early Career — Infineon Technologies, India

Automotive-industry engineering experience prior to relocating to Germany for graduate studies.

M.Sc. INFOTECH (Embedded Systems)

Universität Stuttgart, Germany · Oct 2023 – Jul 2026

B.E. Electrical & Electronics Engineering

Anna University, India · Aug 2015 – Apr 2019

  • Deep Learning Specialization — Coursera
  • Multi-GPU Deep Learning — NVIDIA
  • TinyML & Efficient Deep Learning Computing — MIT
  • ARMv8-A Exception Handling & Kernel Crash Debugging — Udemy

Let's build something fast.

Open to C++/GPU engineering roles. Reach out directly — I reply quickly.